Working with AI is the new skill.
See who can build production-grade with AI, not just vibe-code.
- See how they think, plan, iterate, and correct AI — applying real skills, not just vibe-coding.
- Measure human contribution, domain knowledge, and independent understanding — for every role.
- In a real AI IDE, with proctoring and anti-cheat so the signal is real.
- Fix your AI-slop resume problem — save recruiters and tech panels from buring out.
Old signals measure a proxy. New signals measure the work.
Resumes & video Q&A can't predict who can actually build.
We tested candidates against their own resumes — the stronger the resume, the wider the gap.
Skills-based assessment closes the gap.
Give candidates a real task in a real AI IDE and measure what they can actually ship — not what they claim.
The 6 AI-fluency dimensions we score live in the section below — one place, no repeats.
From 1,000 candidates to your top 5.
Give everyone the same production task, see exactly what they build, then review a scored report in 5 minutes — hours saved per hire.
Everyone gets the same real production task.
They plan, iterate, and build production-grade work in a real AI IDE.
See exactly what they built and how they used AI — scored, not guessed.
Only the real builders reach your calendar.
Working with AI is the new skill.
And the only way to measure it is to watch someone actually do it — on a real task, in a real AI workspace.
Vague goal → agent output → accept result → wrong deliverable.
Clear goal → constrained task → validate → correct → iterate.
Know enough to judge whether the AI is solving the right problem.
Translate ambiguity into constraints, acceptance criteria, and edge cases.
Break large goals into testable, reviewable units of work.
Balance implementation with user value, UX tradeoffs, and product intent.
Prompt with context, constraints, examples, and iteration loops.
Independently inspect, test, fact-check, debug, and redirect AI output.
Real tasks. Real AI tools. Real signal.
Engineers, PMs, sales, support, analysts, ops — every role today works alongside AI. VibeLevel measures that collaboration skill across all of them, on the same platform.
CODINGAssess AI Coding skills
 NON-CODING
Assess AI Non-Coding skills
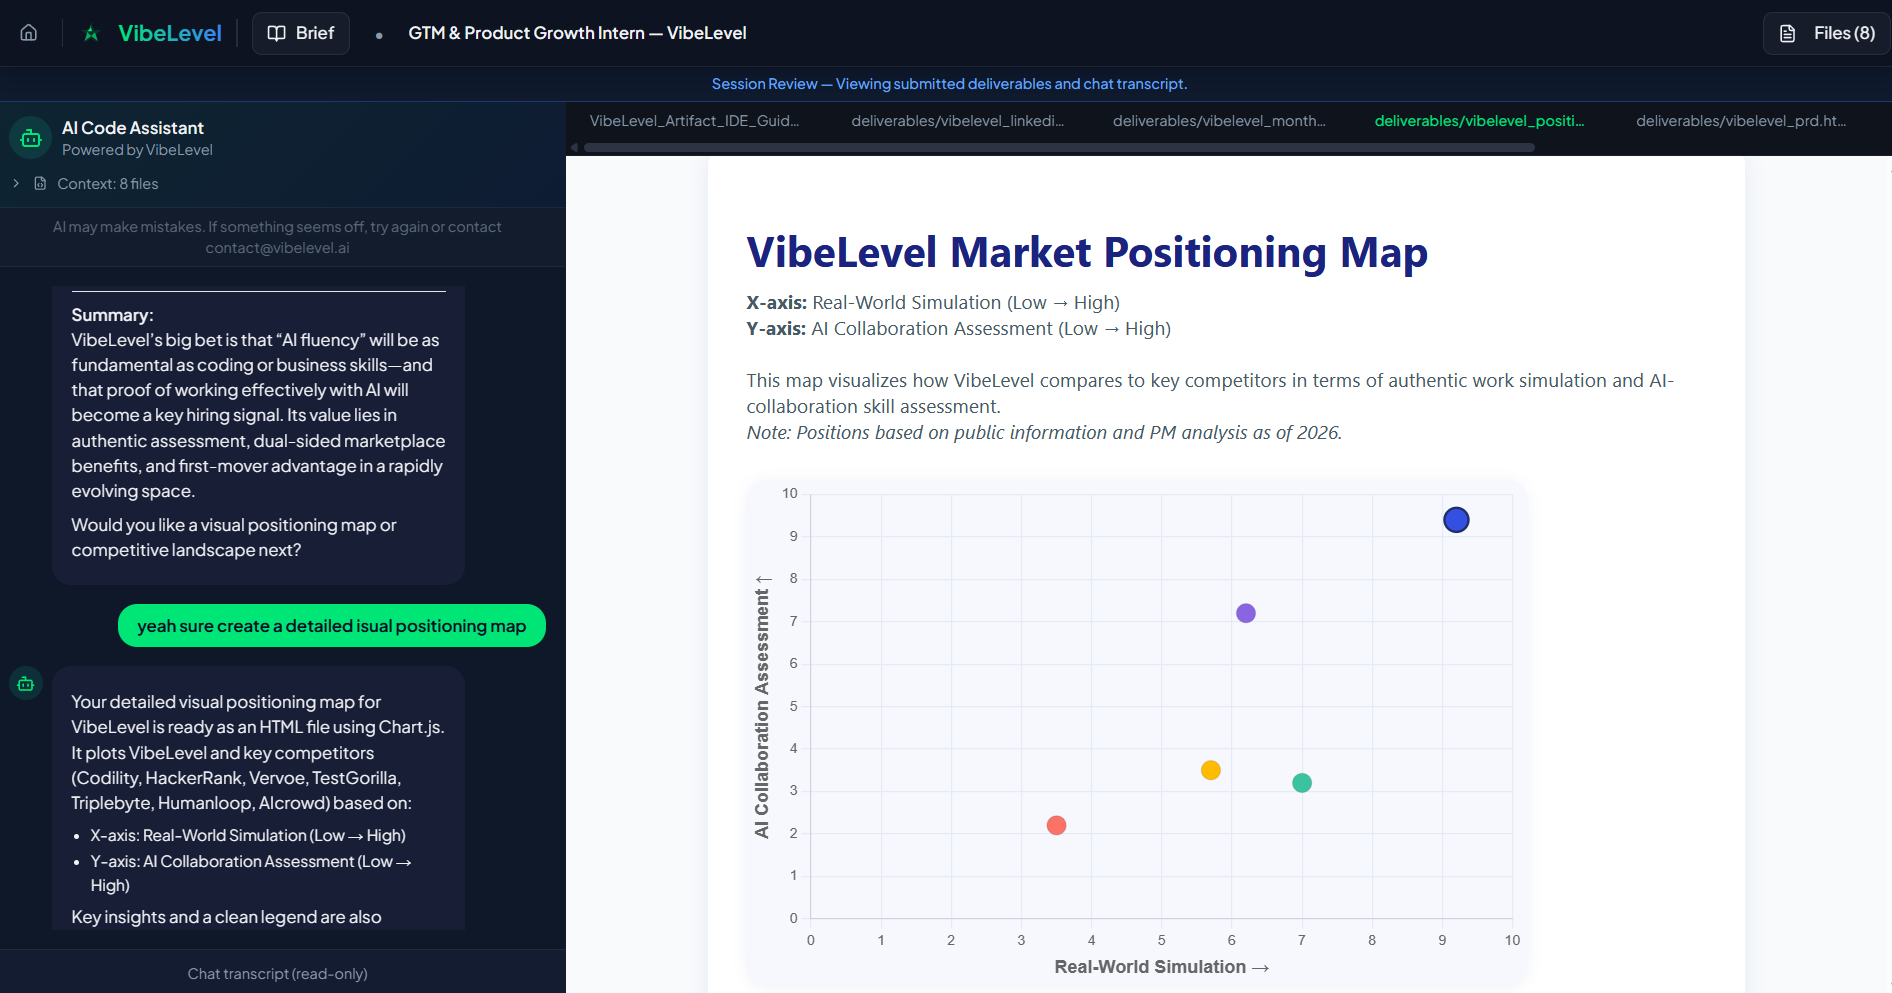
Human-AI collaboration scoring for hiring decisions.
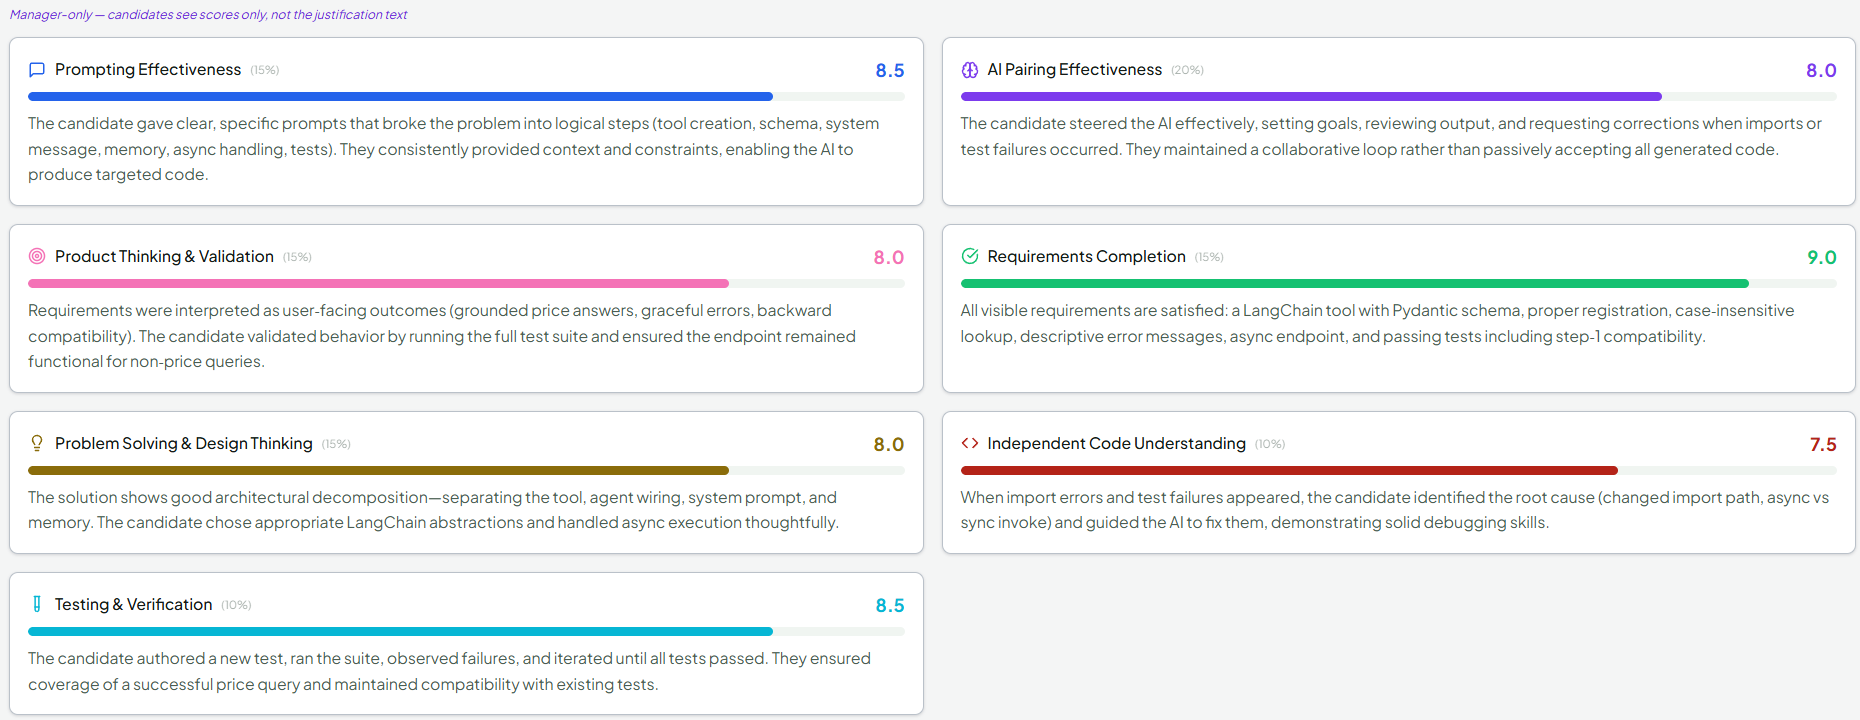
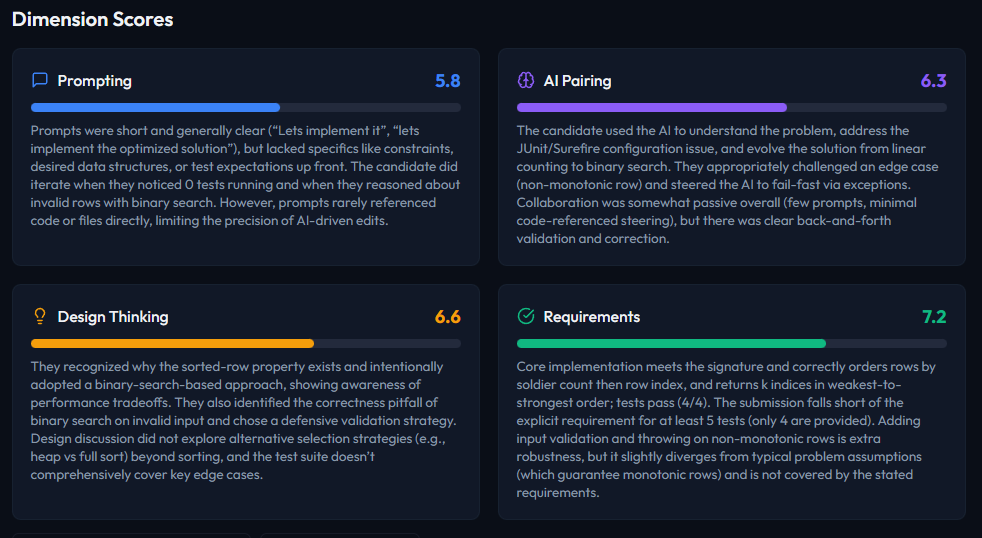
Every assessment is scored across the behaviors that matter in AI-native work: how candidates direct the AI, whether they understand the output, and whether the final deliverable actually meets the brief.
Prompting
How clearly the candidate frames tasks, adds context, and iterates with the AI.
AI Pairing
How well the candidate steers, collaborates with, and course-corrects the AI.
Product
Whether the candidate solves the right problem and validates the user outcome.
Requirements
How fully the final submission meets the task requirements and constraints.
Design / Strategic Thinking
Decomposition, architecture, tradeoffs, and conceptual understanding.
Code Understanding
Ability to read, debug, and modify code independently, not just accept AI output.
Testing / Deliverable Quality
Use of tests, previews, validation, and polish before submitting the work.
Human Contribution Score
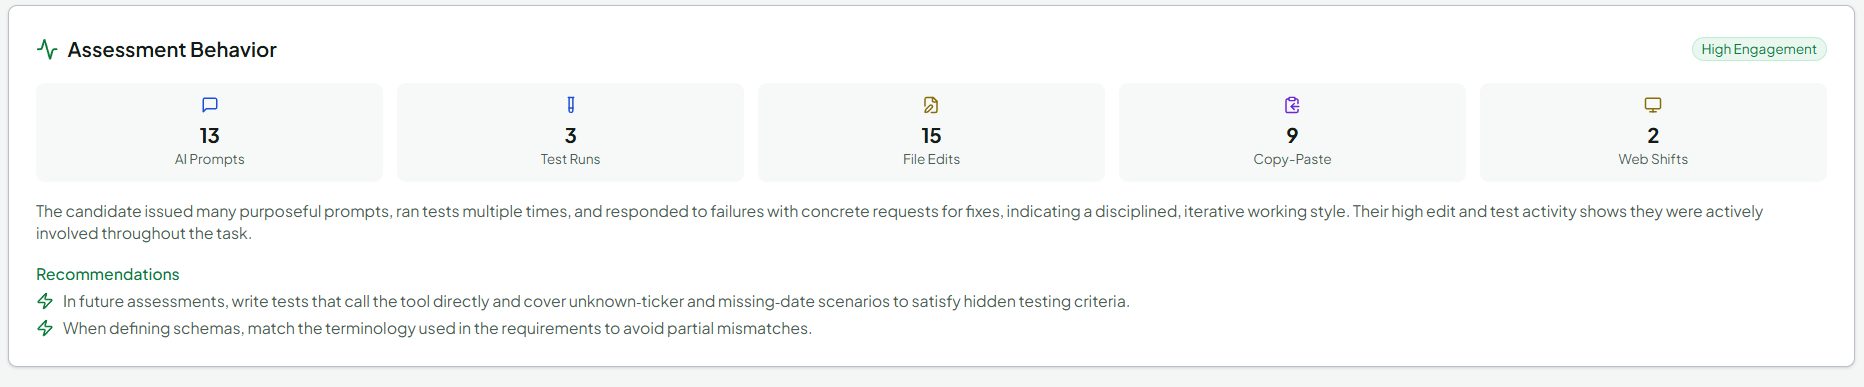
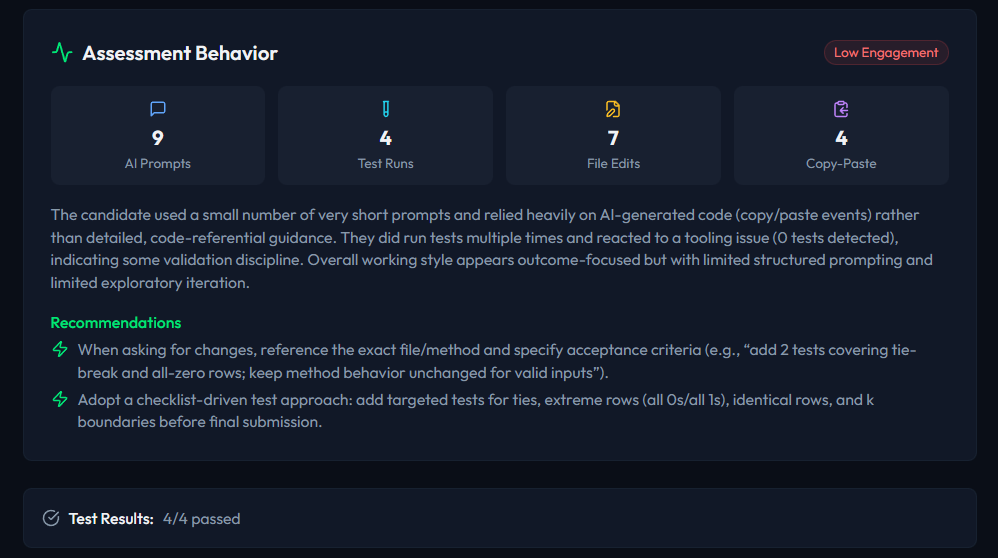
VibeLevel combines score dimensions with behavior telemetry: prompts, edits, test runs, paste events, file activity, and engagement. Hiring teams can see whether the candidate drove the work or passively accepted AI output.
From job req to ranked shortlist. In days, not weeks.
Four steps. No extra tooling. Fits inside your existing ATS workflow.
Describe the role
Tell the AI builder what the job requires. Get a task-based assessment — API integration, data analysis, product brief — in under 5 minutes. No template wrestling.
Trigger from Ashby or Lever
Connect your ATS in one click. When a candidate hits your screening stage, the assessment fires automatically. Or just paste the link into your existing email.
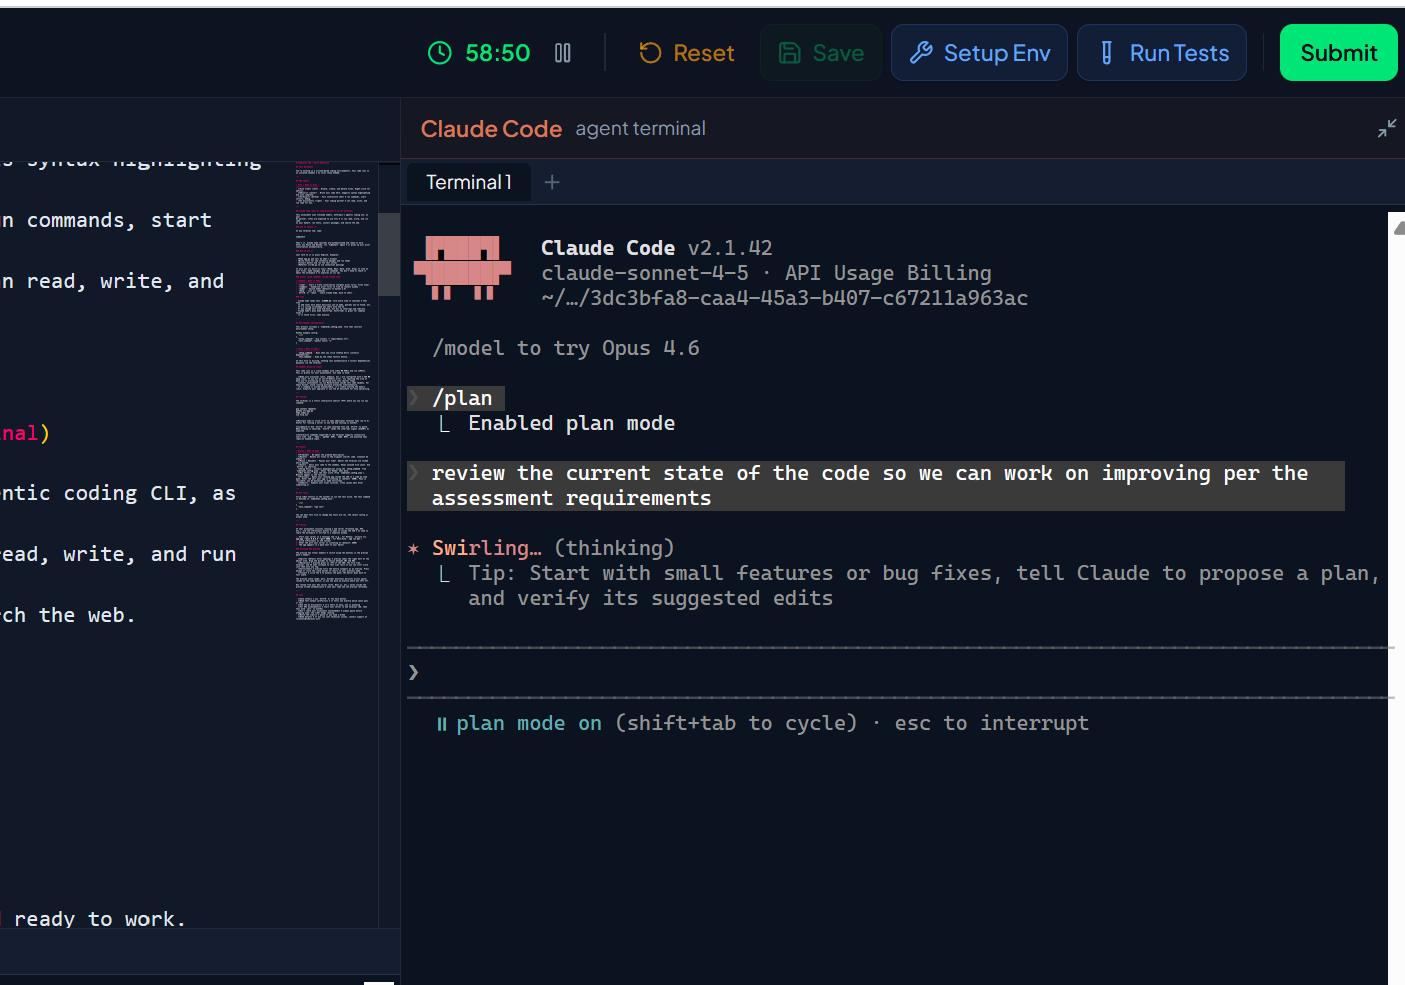
Candidates work in a real AI IDE
20–45 minutes in a Claude Code-style workspace. Real AI tools, real file tree, real terminal. Proctored. Identity-verified. You see every move.
Get your ranked shortlist
AI scores across 7 dimensions. See who can build, who leaned entirely on AI, and who's ready for your team. Interview only the standouts.
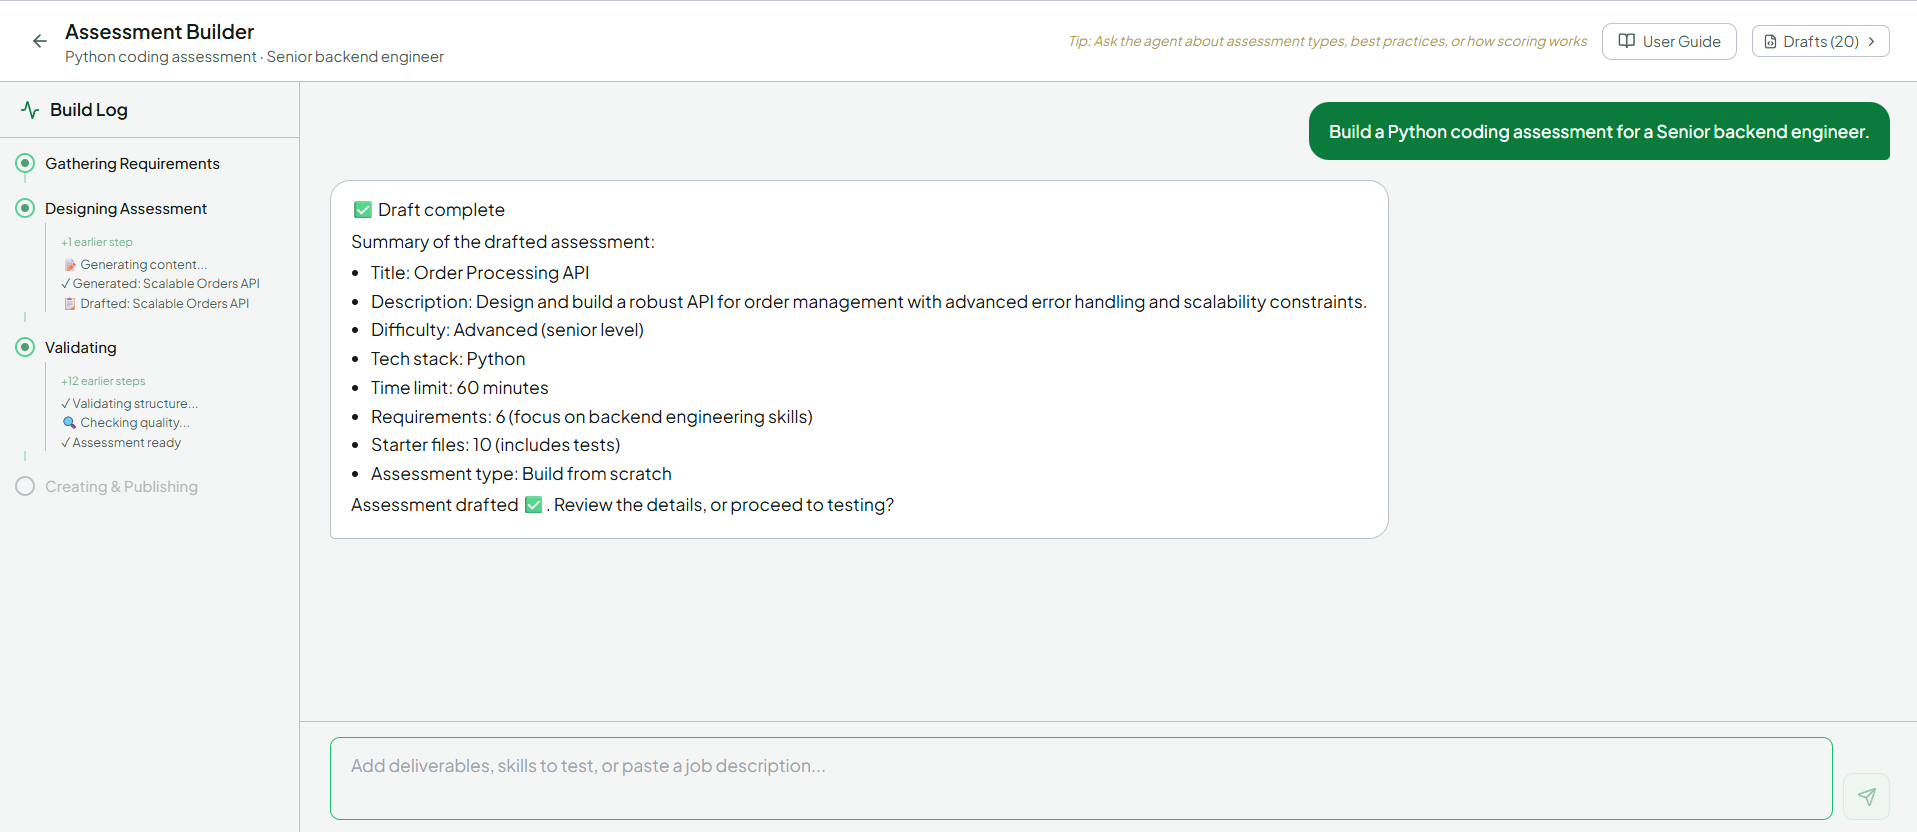
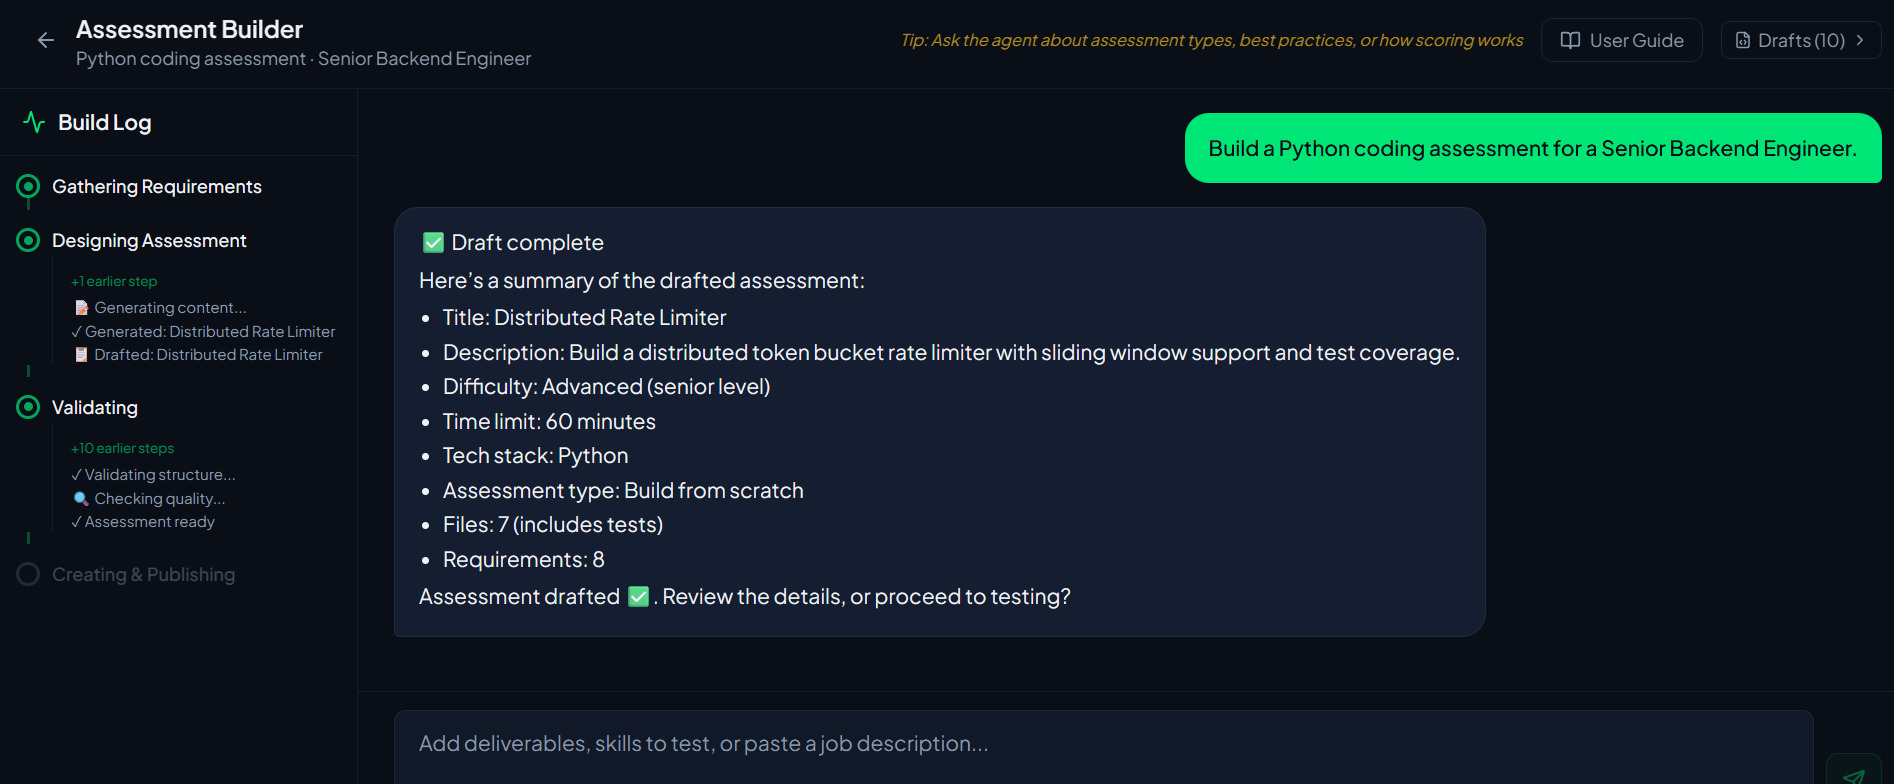
Chat your assessment into existence.
Describe the role, skills, rubric, and constraints. VibeLevel turns that into a task-based assessment, validates it in a live sandbox, and publishes a candidate-ready test without template wrangling.
Fits your workflow. Zero friction.
Native Ashby and Lever integrations. Trigger assessments from your pipeline stage — results flow back into candidate profiles automatically.
 AshbyNative
- Trigger assessments directly from any pipeline stage
- Candidate scores sync back to the Ashby profile
- No double-entry. No new tab. No workflow disruption.
 LeverNative
- One-click activation in Lever integration settings
- Assessment results appear as structured candidate notes
- Works alongside your existing Lever setup — not a replacement.
Built-in detection for external AI tool use.
Every session is observed by a multi-signal detection layer that flags external AI tool use — ChatGPT, Claude, browser side-panels, automation, and more. Each session ships with a confidence-graded summary so reviewers see the strength of evidence at a glance.
External Assistance Detected — Low Confidence (14 / 100) · 1 signal
Indicators that the candidate may have used external AI tools instead of relying solely on Claude Code, VibeLevel's built-in AI assistant. Higher confidence means stronger evidence.
External Assistance Detected — Medium Confidence (38 / 100) · 2 signals
Indicators that the candidate may have used external AI tools instead of relying solely on Claude Code, VibeLevel's built-in AI assistant. Higher confidence means stronger evidence.
External Assistance Detected — High Confidence (64 / 100) · 3 signals
Indicators that the candidate may have used external AI tools instead of relying solely on Claude Code, VibeLevel's built-in AI assistant. Higher confidence means stronger evidence.
We deliberately don't publish specific detection methods to keep the system honest.
Make sure the right person took the assessment.
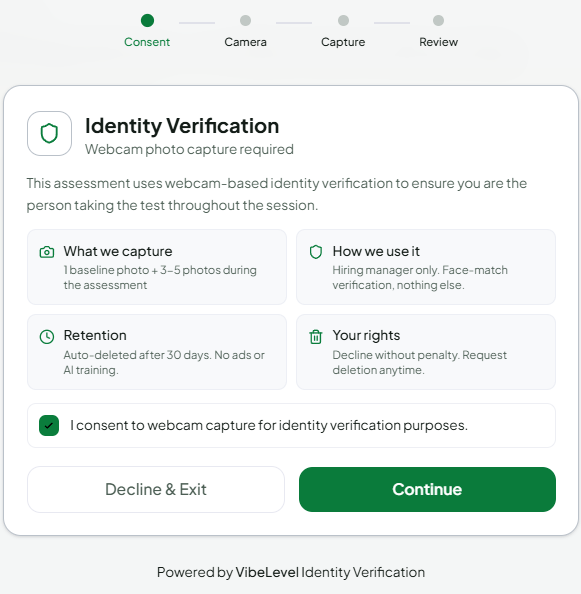
Two complementary checks: a live photo capture during the session, and an optional LinkedIn-verified profile. Together they make impersonation expensive and accountability simple.
Live photo capture during the assessment
A baseline photo is captured at the start of the session and verified throughout. Reviewers see the photos and a verified / rejected decision inline with the score report.
Verified profile on every submission
Candidates sign in with LinkedIn; their verified name, photo, and headline are attached to the session. Hiring teams get a real human behind every score, not just an email address.
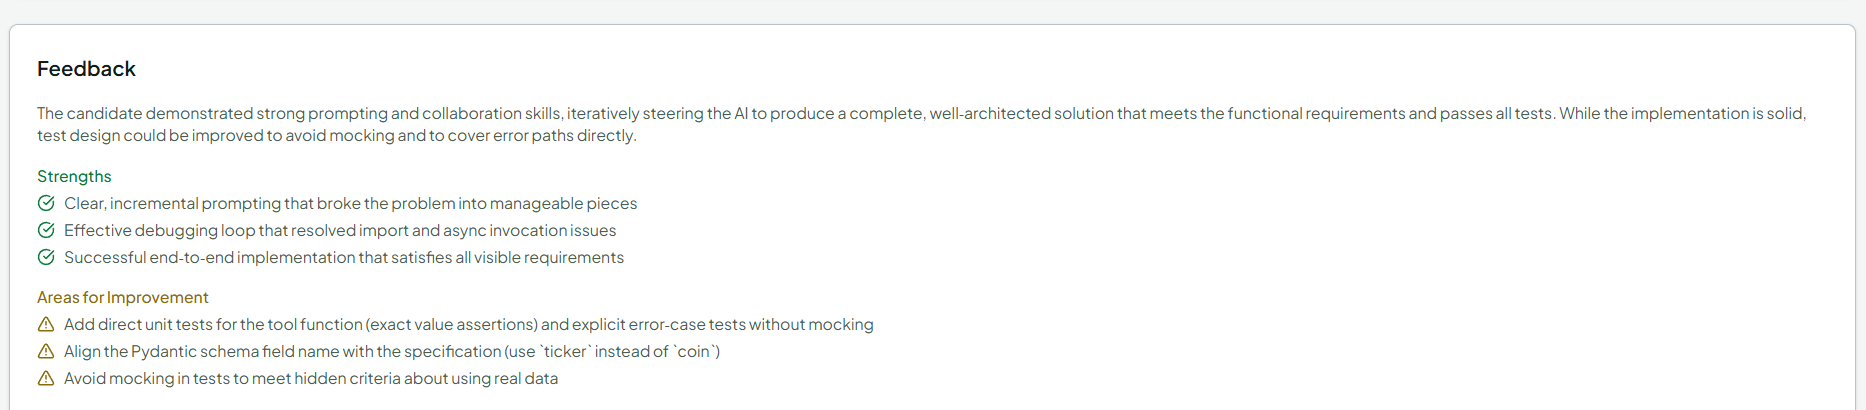
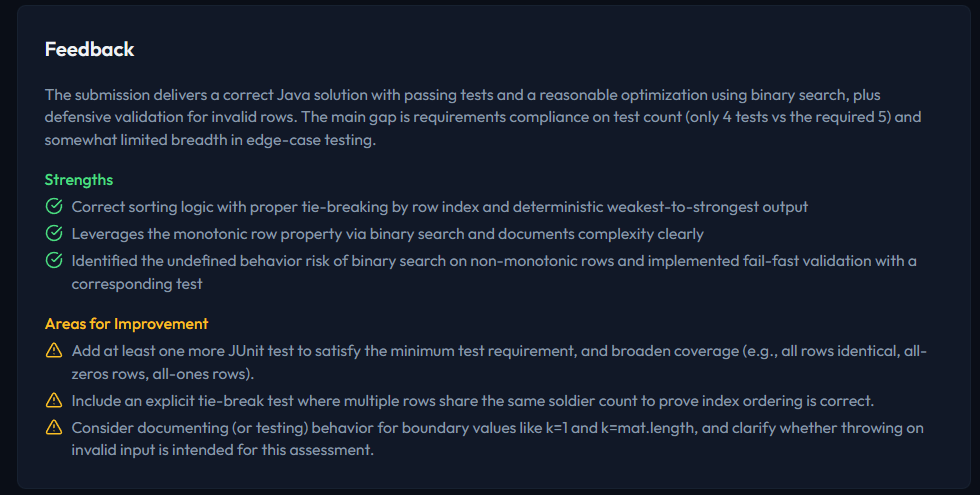
Structured assessment report with multi-dimensional scoring plus a Human Contribution label so it is clear what the candidate did vs. what the AI did.
2–3× more capability at 50% less cost. Structured Assessments with an agentic hiring funnel built in — not bolted on — plus Aura session scoring on the same platform.
| Feature | Others | VibeLevel.ai |
|---|---|---|
| AI Coding Agent (Copilot-class) | ||
| AI Non-Coding Assessments (Claude-class) | ||
| Full IDE (editor, terminal, file tree) | Basic | |
| AI-Native Assessment Scoring | ||
| Human Contribution Detection | ||
| Anti-Cheating & Proctoring Signals | Basic | |
| AI Resume Scoring | ||
| End-to-End Hiring Funnel | ||
| Agentic Auto-Filter & Screening | ||
| Application Forms & Resume Collection | Add-on | |
| Multi-Dimensional Scoring | ||
| Custom AI Agent Persona | ||
| Candidate Comparison & Ranking | Limited | |
| Campus Vibeathons & Talent Pipeline | ||
| Algorithm / LeetCode-style Tests | Supported + AI | |
| Pricing | $300–$500/seat/yr | Pay-as-you-go |
| Free Tier | Limited | Generous |
From 1,000 applicants to 3 finalists.
Pick your path. Measure what matters, not just vibes — you interview only the standouts.